The Origin of Z-Image
Unified 6B Parameter Foundation
Welcome to the official Z-Image interface. Experience the original single-stream DiT architecture that seamlessly unifies text comprehension and visual generation into one powerful flow.
The Z-Image Foundation
Z-Image represents a paradigm shift in generative AI, engineered by the researchers at Tongyi-MAI. Unlike traditional stacked models, Z-Image introduces a proprietary 6 Billion (6B) Parameter core that operates as a singular, cohesive unit.
At its heart lies the Single-stream Diffusion Transformer (DiT). This original architecture eliminates the separation between text encoding and image decoding, allowing Z-Image to "think" in visuals and language simultaneously. The result is a model that offers industrial-grade photorealism on consumer hardware.
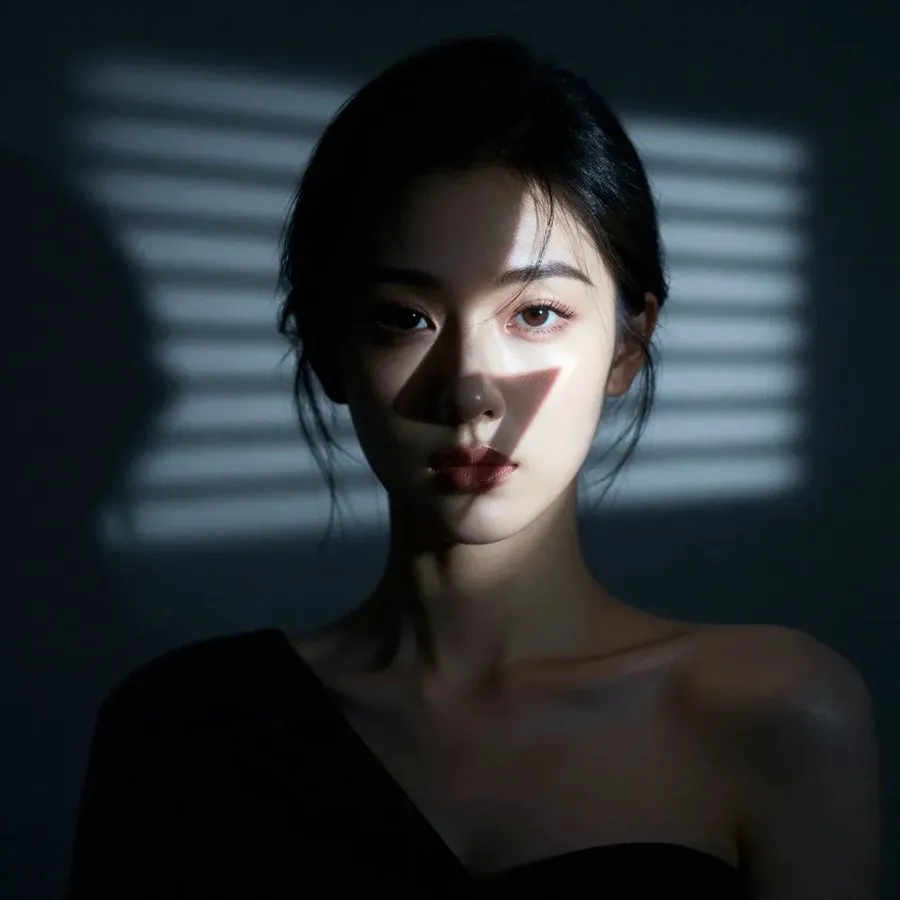
Core Attributes of Z-Image
The specifications that define the Z-Image standard.
Z-Flow Efficiency
Leveraging advanced distillation techniques, Z-Image achieves convergence in approximately 8 sampling steps. This is the "Flash-Step" capability exclusive to the Z-Image-Turbo variant.
Native Bilingualism
Z-Image does not translate; it understands. Trained on a massive corpus of diverse data, it offers native fluency in both Chinese and English prompting and typography.
Unified 6B Architecture
The Single-stream DiT is the hallmark of Z-Image. This 6B parameter configuration ensures maximum feature retention while maintaining a VRAM footprint compatible with 16GB GPUs.
Z-Image Comparative Analysis
Benchmarking the Z-Image unified core against legacy generation methods.
| Specification | Z-Image (The Original) | Legacy Models (SDXL/Nano) |
|---|---|---|
| Core Architecture | Single-Stream DiT (Unified) | Dual-Stream UNet (Split) |
| Linguistic Engine | Deep Bilingual (CN/EN) | English Centric |
| Generation Latency | ~8 Steps (Flash-Step) | 25-50+ Steps |
| Hardware Profile | 16GB VRAM Optimized | High-End Data Center Heavy |
The Z-Image Application Ecosystem
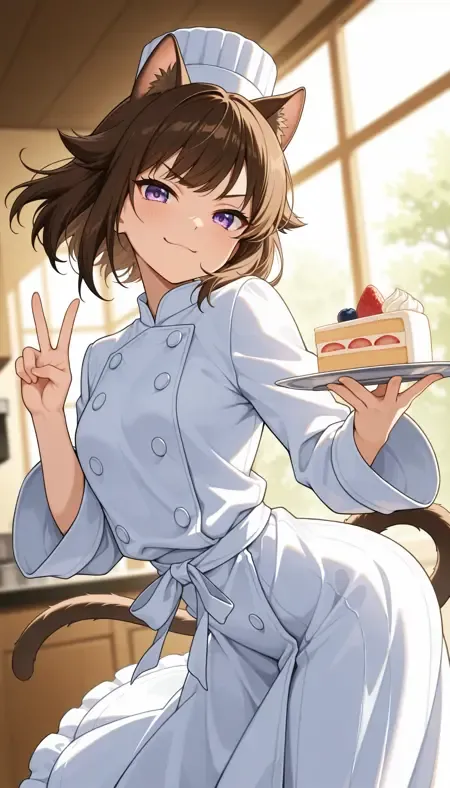
Identity Preservation
Z-Image maintains character features across varying styles.
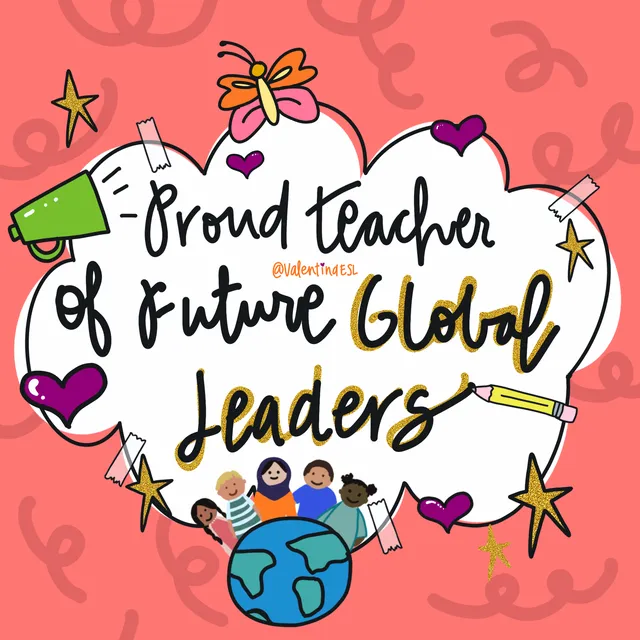
Typography Rendering
Flawless Chinese & English text integration by Z-Image.
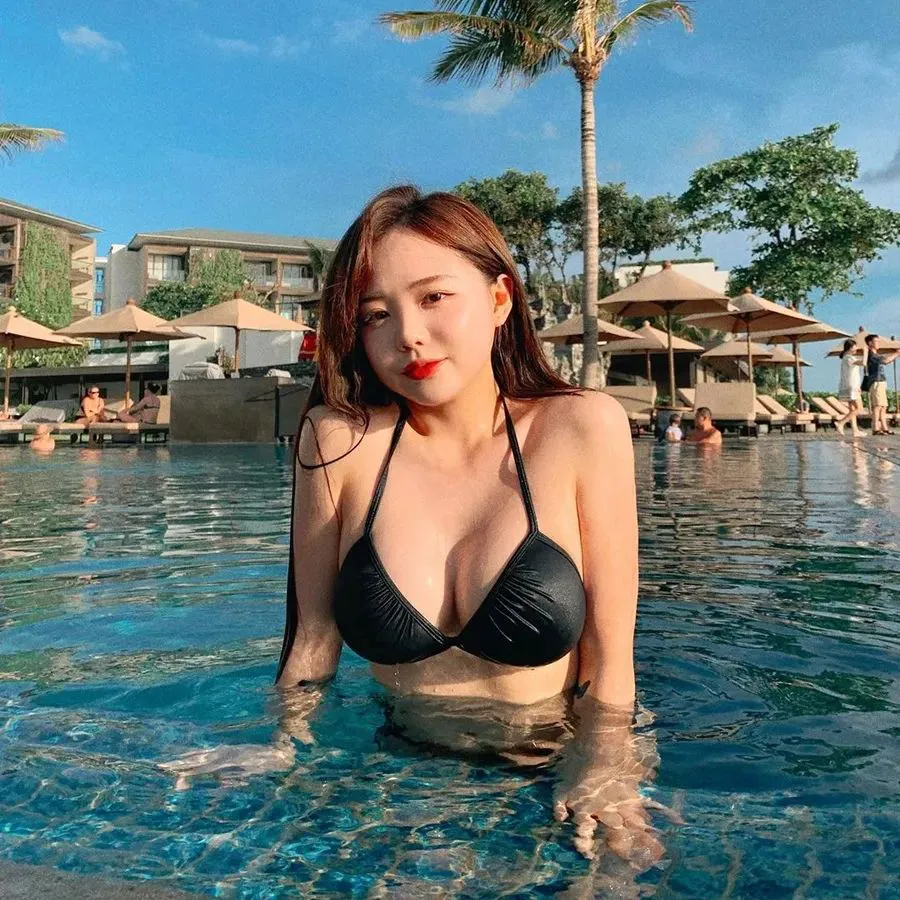
Cinematic Fidelity
6B parameters dedicated to lighting and texture.

Rapid Concepting
Instant visualization with Z-Image-Turbo.
Z-Image Technical FAQ
Insights into the Tongyi-MAI Z-Image foundation model.